Published 6 October 2026, based on the midPoint 4.11 preview and the documentation available at that date. The 4.11 final release is currently planned for 15 October 2026, and details may still change.
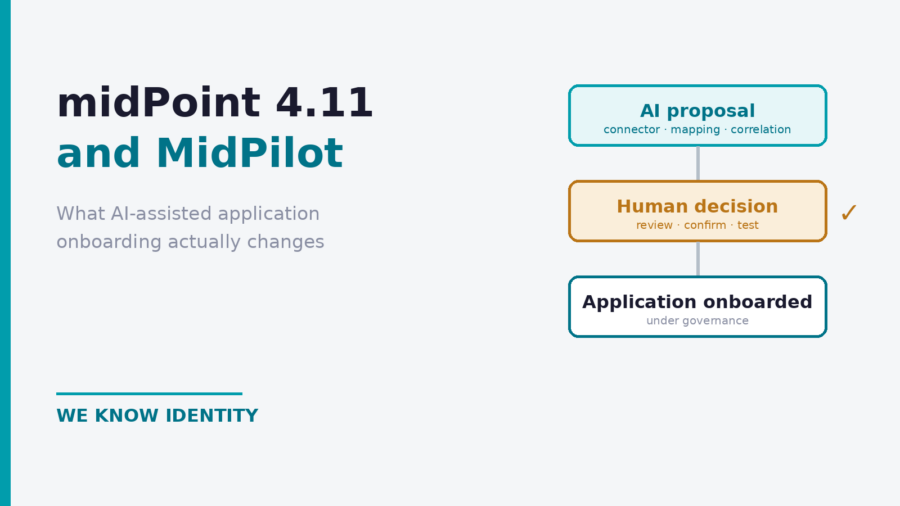
midPoint 4.11 is currently scheduled for final release on 15 October 2026. Its June preview already gives a practical look at the MidPilot outcomes planned around 4.11: an AI-assisted connector code generator, recommendation services for mappings and correlation, an integration catalog, and reworked onboarding wizards. We have been testing those capabilities ahead of the final release. What they appear set to change is the effort side of connecting applications: the repetitive integration work that made onboarding slow gets machine assistance. What does not change is just as important: mapping and correlation recommendations require a final user decision by design, results still depend on the quality of your identity data, and generated connectors still need engineering review and testing against real systems. This article covers both halves.
Why application onboarding is the bottleneck
Many IGA programs still have only a subset of the organization’s applications connected to the platform. The reasons are structural. Every application needs integration code for its protocol and quirks, attribute mappings between its data model and the identity model, and correlation rules that match its accounts to real people. Each of those steps takes specialist time, and organizations run hundreds of applications. Integration engineering effort is one of the major contributors to the resulting backlog, alongside missing ownership, absent APIs, weak documentation, and governance ambiguity. The combined effect is the same: the important systems get onboarded, and a long tail of applications waits indefinitely.
That long tail is not a cosmetic gap. Applications outside the IGA platform can also remain outside centralized lifecycle automation, access review, and governance visibility, whatever local processes they may have. Evolveum’s project page frames the motivation the same way, citing weak visibility from slow and incomplete application onboarding as a key identity security issue. Our first two articles this quarter dealt with the same phenomenon from other angles: unmatched accounts that nobody classifies, and identity operations that quietly stop while dashboards stay green.
What MidPilot actually delivers
MidPilot was a fourteen-month Evolveum project, funded by the European Union through the Recovery and Resilience Plan of the Slovak Republic, running from April 2025 to May 2026. Its outcomes reached the public in the midPoint 4.11 preview in June 2026, with production quality planned for the 4.11 final. Four deliverables matter operationally:
A connector code generator service. The service generates integration code using contextual information about both the application being integrated and the connector framework: object and schema detection, identity and access management operations, and help with connector configuration options. It targets cloud services as well as on-premise applications, and object types beyond users: groups, organizational units, memberships.
A recommendation service for mappings and correlation. The mapping side proposes attribute matches, from simple name translations across languages and abbreviations up to transformations, value composition, and scripting logic, including proposals for schema extensions when no matching midPoint attribute exists. The correlation side suggests correlation keys and rules: linking users to accounts, groups to roles, memberships to assignments. Both are explicitly interactive and iterative, and both always require the user’s confirmation. Evolveum designed the human into the loop, not around it.
An integration catalog. A place to browse, share, and reuse not only connectors but also mapping configurations and correlation rules. Reuse is quietly the most economically interesting part: the second organization onboarding the same SaaS application should not start from zero.
Reworked onboarding UI. A new wizard for connector generation, reworked wizards for mapping and correlation configuration, and integration of the same capabilities into midPoint Studio for advanced users and integrators.
Our first-hand impressions from working with the preview: connector generation currently targets SCIM and REST interfaces, built on Evolveum’s SCIMREST framework, which is public in their repositories and which Evolveum still describes as evolving. In the cases we tested with good API documentation, we found the generator genuinely useful: much of the initial integration scaffolding stopped being the main pain point. What stays firmly with you is testing, and plenty of it. On the AI side, one clarification worth making precisely: the MidPilot services require an LLM, with some mapping suggestions also available from built-in heuristics. The enterprise-relevant detail is that the LLM endpoint is OpenAI-compatible, so it can be self-hosted. Organizations that do not want their IGA platform talking to an external AI service can run the model inside their own boundary and point the services at it.
What you actually have to deploy
4.11 does not ship a magic embedded AI engine, and that is worth understanding before anyone plans an upgrade around it. The AI-assisted MidPilot capabilities rely on optional external services that midPoint connects to: the smart resource integration service for mappings and correlation recommendations, and the connector generator service. They require their own configuration and infrastructure, and the connector generation service carries additional dependencies of its own, including a PostgreSQL instance and an LLM endpoint.
The architecture, roughly: midPoint 4.11 talks to the Smart Integration services, which talk to an LLM endpoint. At that last hop you have a real choice: an external AI service, or a self-hosted model behind an OpenAI-compatible endpoint. Which one is right depends on your security and data-governance requirements, because the services work with your schemas, sample identity data and, for connector generation, target API documentation and related integration context. For many European organizations we work with, the self-hosted option is the difference between “interesting feature” and “feature we are allowed to use.” One more architectural detail worth knowing: the services should be treated as trusted internal components and isolated accordingly, because Evolveum’s current reference deployment does not enable authentication on the midPoint-facing microservice endpoints by default, so network and secrets controls around the deployment are part of the design. Plan the deployment question alongside the upgrade question, not after it.
What this changes in practice
The honest framing is that MidPilot attacks the effort side of onboarding, which is one of the main reasons backlogs exist, though not the only one.
More of the long tail can become economically viable to onboard. When a connector plus mappings plus correlation for a routine application takes days of specialist effort, only important systems clear the bar. Machine-assisted generation and recommendations lower the per-application effort, which moves the break-even point down the tail. Where onboarding is blocked by missing ownership or an absent API rather than effort, the AI changes nothing, which is precisely why the preparation section below exists.
Iteration gets faster where it used to be slow. Mapping and correlation design has always been an iterate-and-verify loop: propose, check against real data, adjust. Recommendations that start the loop close to a workable answer, combined with midPoint’s simulations for verifying the post-change state before executing it, compress the loop without removing its checkpoints.
Reuse becomes a first-class mechanism. The integration catalog turns onboarding knowledge into an asset that accumulates. For integrators like us, that changes delivery too: the value shifts further toward the judgment calls, the nonstandard systems, and the governance decisions, and away from retyping boilerplate.
What this does not change
This is the part vendor marketing tends to skip, so it is the part worth writing down.
Human confirmation is the design, not a limitation. Mapping and correlation recommendations require a final user decision by design, while generated connector artifacts still require engineering review, refinement, and testing. That is the correct design for anything that decides how access is granted and matched. The person confirming needs to understand what they are confirming: an AI proposal accepted blindly is just manual misconfiguration at higher speed.
Data quality still decides correlation quality. The recommendation services are built to cope with typos, missing values, and inconsistencies, but coping is not curing. Recommendations operate on the schemas and sample data available to them, so ambiguous or inconsistent source data can still produce ambiguous proposals that a human has to resolve. Everything in our identity data quality article applies before AI-assisted onboarding, not instead of it.
Generated code still needs testing. A generated connector is a starting point that has to be verified against the real application, its real API behavior, its rate limits, and its edge cases, in a proper test environment with test endpoints. The environments discipline from our operations article applies unchanged: production remains the place where nothing happens for the first time.
Governance decisions stay human. Which accounts should exist, who approves access, how roles are structured, what happens on offboarding: none of this is a mapping problem. Faster onboarding gets applications under governance sooner, and then the governance itself still has to be designed and owned.
How to prepare before 4.11 lands
If AI-assisted onboarding lowers the per-application effort, the winners will be organizations whose backlog is ready to be worked through. Concretely:
- Inventory the unconnected. List the applications not yet under governance, with an owner per application. If the responsibility map from go-live exists, this is fast; if not, this is the moment to build it.
- Prioritize by risk, not convenience. Applications holding sensitive data or privileged access first, regardless of how easy they are to connect.
- Clean the identity data. Correlation recommendations work with the identifiers and attributes you have. The stable-identifier and classification work pays off directly here.
- Have the test environment ready. Generated connectors and proposed mappings need somewhere safe to be verified.
- Plan the AI deployment question. External AI service or self-hosted OpenAI-compatible endpoint, and who signs off on schemas and sample data flowing to it. This is a security decision, and it is faster to make before the upgrade than during it.
- Decide your 4.11 position. 4.11 is a feature release, not an LTS. Deployments following feature releases get the Smart Integration outcomes on upgrade. Deployments staying on 4.8 LTS have a strategy decision to make: wait for the next LTS, or move to the feature-release track earlier because the onboarding gains justify it. That is a business decision about backlog size, not a technical default.
Frequently asked questions
When is midPoint 4.11 released?
The 4.11 final release is currently planned for 15 October 2026, following the preview released in June 2026. Evolveum states plainly that planned dates are estimates, so check their roadmap for the current status.
Will the AI build connectors for me automatically?
It generates connector code using context about the application and the connector framework, and it proposes mappings and correlation rules. Mapping and correlation recommendations require a final user decision, while generated connector artifacts still need engineering review, refinement, and testing against the real system before production use. Assistance, not autonomy, and deliberately so.
Does this require sending our data to an external AI service?
The Smart Integration services require an LLM, and the endpoint is OpenAI-compatible, so it can be an external service or a model you host yourself. Some mapping suggestions can also come from built-in heuristics. Organizations with strict data-governance requirements can keep LLM processing inside their own boundary by hosting an OpenAI-compatible inference endpoint. The connector generator may still require controlled outbound access for API-documentation discovery and framework artifacts, depending on how it is deployed.
We run 4.8 LTS. Should we move for this?
Not automatically. 4.8 is supported until October 2028, and the next LTS is the conservative path. The case for moving earlier is a large onboarding backlog whose effort the new capabilities would materially cut. Note the upgrade path too: direct upgrade to 4.11 is supported from 4.10.x. Older versions must first be upgraded to 4.10.3, so moving from 4.8 LTS is a staged upgrade project. Size it honestly before deciding.
Does AI-assisted onboarding replace connector development?
It changes where the effort goes. Routine SCIM and REST integrations need less hand-written boilerplate, and specialist time concentrates on nonstandard systems, complex transformations, correlation edge cases, and verification. For custom and legacy applications with unusual interfaces, engineered connectors remain the path.
Get your backlog ready
The organizations that will benefit most from 4.11 are the ones whose application inventory, identity data, environments, and AI deployment decisions are ready before it arrives. We help with exactly that: onboarding backlog assessment, identity data preparation, connector development for the systems AI will not cover, and the 4.11 upgrade decision itself.
Discuss your application onboarding backlog
Related Resources
- midPoint Connector Development
- Building Custom midPoint Connectors for REST APIs
- Identity Data Quality Before Automation
- Operating midPoint in Production
- midPoint Consulting and Implementation Services
Sources
- Evolveum: MidPilot Project. Project goals, four deliverables, user-confirmation design, EU funding via the Recovery and Resilience Plan of the Slovak Republic.
- Evolveum: MidPoint 4.11 Release Page. Planned October 2026 feature release; upgrade path (direct from 4.10.x, older versions via 4.10.3); planned-release disclaimer.
- Evolveum: MidPoint Roadmap. Current release planning and dates.
- Evolveum: SCIMREST Framework. The connector framework behind the generated SCIM and REST connectors.
- Evolveum: connector-scimrest on GitHub. Public sources of the SCIMREST framework.
- Evolveum: midpilot-connector-gen on GitHub. Connector generator service: PostgreSQL requirement, OpenAI-compatible LLM configuration, Docker Compose deployment.
- Evolveum: MidPilot AI Services Setup. Two-microservice architecture, LLM requirement and OpenAI-compatible endpoint, connector-generator PostgreSQL requirement, Internet and search access, framework artifact, default lack of authentication on midPoint-facing endpoints.
- Evolveum: Smart Integrations. Current 4.11 reference for AI-assisted correlation and mapping capabilities.
- Evolveum: Long-Term Support. 4.8 LTS support until October 2028; LTS strategy context.
Planning an IAM modernization or migration?
Our midPoint specialists help enterprises implement, migrate, and operate identity governance platforms. Whether you are replacing MIM, SAP IDM, or another legacy system — we can help you plan a structured, low-risk transition.
Discuss Your ProjectJán Minárčiný
Founder & Lead midPoint Consultant | 4x Evolveum Certified
Ján is the founder of WeKnowIdentity, a boutique IAM consulting firm specializing in Evolveum midPoint. He holds four midPoint certifications (Professional, Advanced, Deployment Specialist, Group Synchronization), plus IDPro BoK and GitOps (CGOA) certifications. With 10+ enterprise midPoint deployments across Europe, he writes about IAM strategy, midPoint best practices, and identity governance.
Add a Comment